Architecting Enterprise RAG with Spark, EMR on EKS & Airflow 3
Building a knowledge base on the fly from PDFs, CSVs, Zoom recordings and Open API specs.
Engineering leader building large-scale data and AI products, and the teams behind them.
Software Engineering Manager at Comscore, leading the team behind production AI for cross-platform audience measurement.
Connect on LinkedIn ↗Prashant Mahajan has spent a decade in data engineering, progressing from building Spark pipelines to leading the team that runs production AI for audience measurement. His earlier work includes a cross-platform campaign measurement product and the migration of a large Spark platform from on-prem Hadoop to AWS.
He has hired 18 engineers and mentored more than 20, and regards developing engineers as the most important part of the role. Outside work, he enjoys hands-on DIY projects at home, a habit that keeps him focused on simple solutions to difficult problems.
One program, one identity, across every screen.
Viewing data arrives with the same program titled in many different ways. This production system uses AI to resolve more than 10 million titles to a single canonical identity, so viewing on TV and on digital platforms is credited to the same program.
Two years, 40+ Spark jobs, zero downstream disruption.
Migrated batch processing from an on-prem Hadoop cluster to AWS while product delivery continued. Downstream consumers saw no schema changes at cutover, and the legacy cluster was decommissioned.
Campaign measurement, from raw data to client reporting.
Comscore's cross-platform campaign measurement product. Owned the data pipeline end to end and later rebuilt it on AWS. Precomputing shared metrics once, rather than for each report, cut processing time roughly in half.
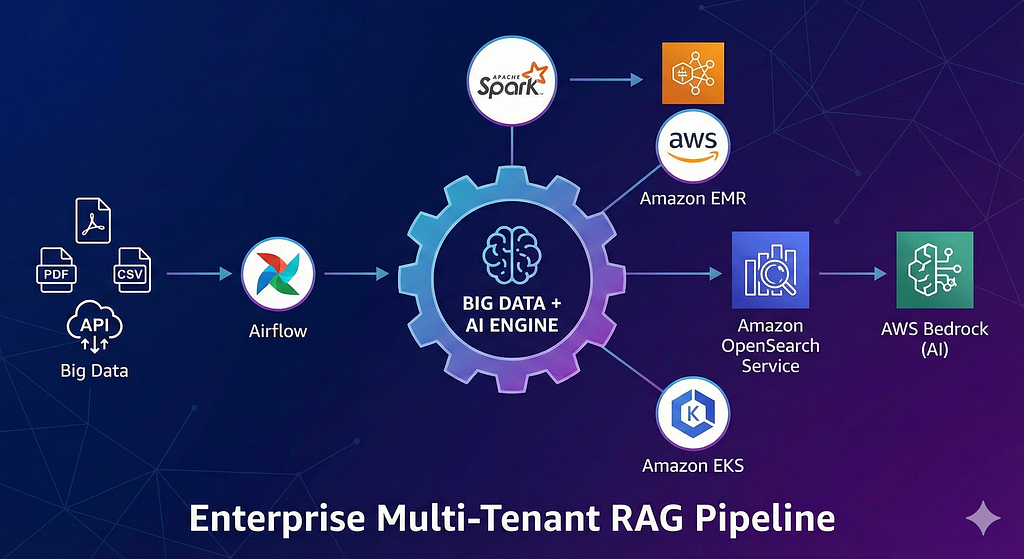
Building a knowledge base on the fly from PDFs, CSVs, Zoom recordings and Open API specs.

Turning probabilistic GenAI into a dependable enterprise analyst with contract engineering and self-healing design.